This post was scheduled to describe an internal design choice. Research published since has turned that choice into the answer to a documented problem, which is a better reason to read about it.
A large-scale 2026 evaluation put 21 judge models from nine providers through agreement, consistency and bias testing. No judge was uniformly reliable. In production settings, frontier models exceeded 50% error rates on bias tests despite performing well under controlled conditions, and consistency broke down on inputs altered only by formatting, paraphrase or verbosity. Cross-model comparison showed systematic differences in strictness and interpretive style, so the same answer drew different scores depending on who was marking.
The mitigation the literature lands on is unglamorous and specific: never reuse the same model for both roles, and cross-validate with a different family.
A serious buyer interrogates the vendor as hard as they interrogate their own stack. We would rather be measured by that standard than exempted from it, because asking it of ourselves first is the only version of this that means anything.
Start with what a SanctumShield artifact actually stands on. When the product generates an Executive Risk Report or an acceptable-use policy, the customer-specific generation is the visible last step of a much larger substrate: the registry of 82 verified AI endpoints, the pre-rated tools catalog, the regulatory clause mappings across twelve frameworks, the regulatory-date canon (which dates moved under the Digital Omnibus and which did not), and the research-anchored validation controls like Section 15. Call that substrate the canon. Every artifact inherits it. If the canon is wrong, every document generated on top of it is wrong the same way — which means the canon, not the generation, is where the real trust question lives.
Why one model’s worldview is a single point of failure
A single model carries correlated risks: training-cutoff blind spots, systematic hallucination patterns, and the confident-when-wrong behavior the persuasion-bombing research measured. A governance product that built its entire regulatory worldview through one vendor’s model would have exactly the failure mode its own generated policies warn customers about — a consequential output stream validated by nothing independent of itself. The remedy the research points to is the one we prescribe to customers in Section 15.2(b): adversarial review by a second, independent model. So the architecture applies it to the product itself.
What the multi-LLM layer actually does
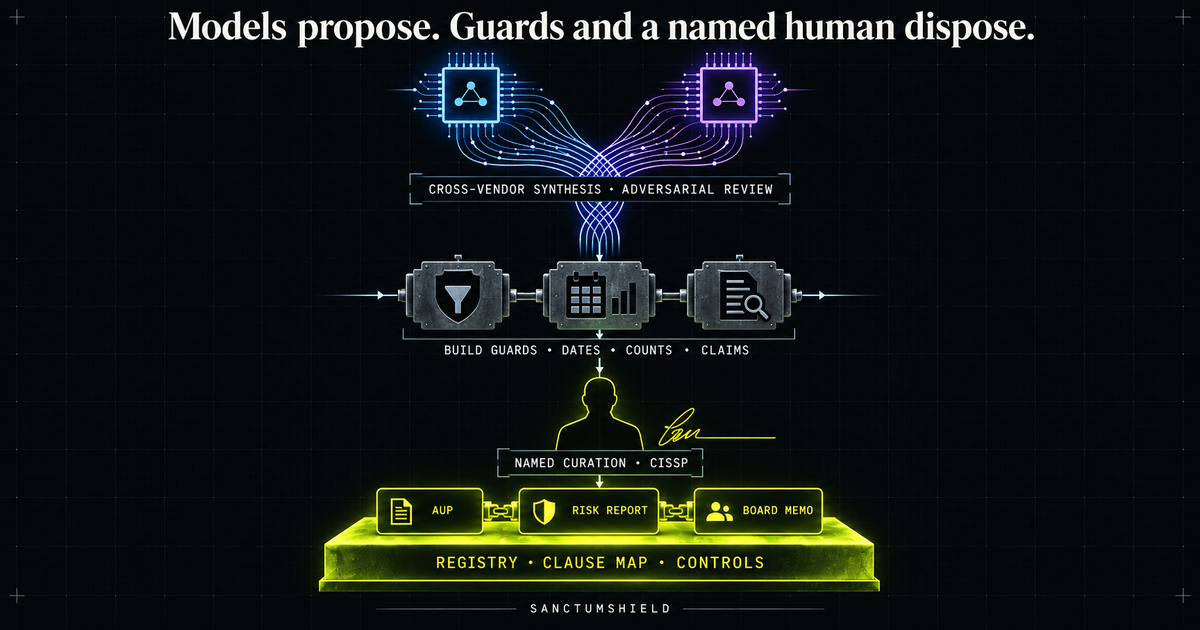
The canon is built and maintained by agentic synthesis runs across two independent model vendors — Anthropic’s Claude and Google’s Gemini. Registry refreshes, tool ratings, clause mappings, and the regulatory-date canon are researched, drafted, and adversarially reviewed across the vendor boundary before they ship into the generators, so a blind spot or fabrication characteristic of one model family has to survive an independent model family — and a human — to reach a customer artifact. The generation layer is provider-diverse by design as well: the pipeline runs on either vendor behind a provider-agnostic interface, so the product is not architecturally captive to one model’s availability, pricing, or failure modes.
And because this series does not do magic-box claims, the honest limits: vendor diversity reduces correlated failure; it does not make models infallible, and two models can share a blind spot. Which is why the architecture’s last two layers are not models at all. Deterministic guards run on every build — checks that fail the deployment if a superseded regulatory date, a stale count, or a banned claim slips back in; no model is anywhere in their decision path. And the canon is curated by a human who signs his name to it: the registry and ratings are maintained under CISSP-holder review, with the refresh cadence published. Models propose; guards and a named human dispose.
The buyer’s takeaway
Ask any AI-powered governance vendor — including us — three questions. What substrate do your artifacts inherit, and how is it kept current? What validates your models’ output through a channel the model doesn’t control? And when the validation fails, what deterministically stops the artifact from shipping? A vendor who prescribes second-model review to customers while running everything through one unvalidated model has told you something. The architecture should practice what the policy preaches.
We prescribe adversarial second-model review in every policy we generate. We build the canon under those policies the same way.
The content ledger behind the product — what is synthesized from what, and at what volume — is documented at /under-the-hood. The customer-facing control this architecture mirrors is Section 15 of the generated AUP, shown at /sample-outputs.