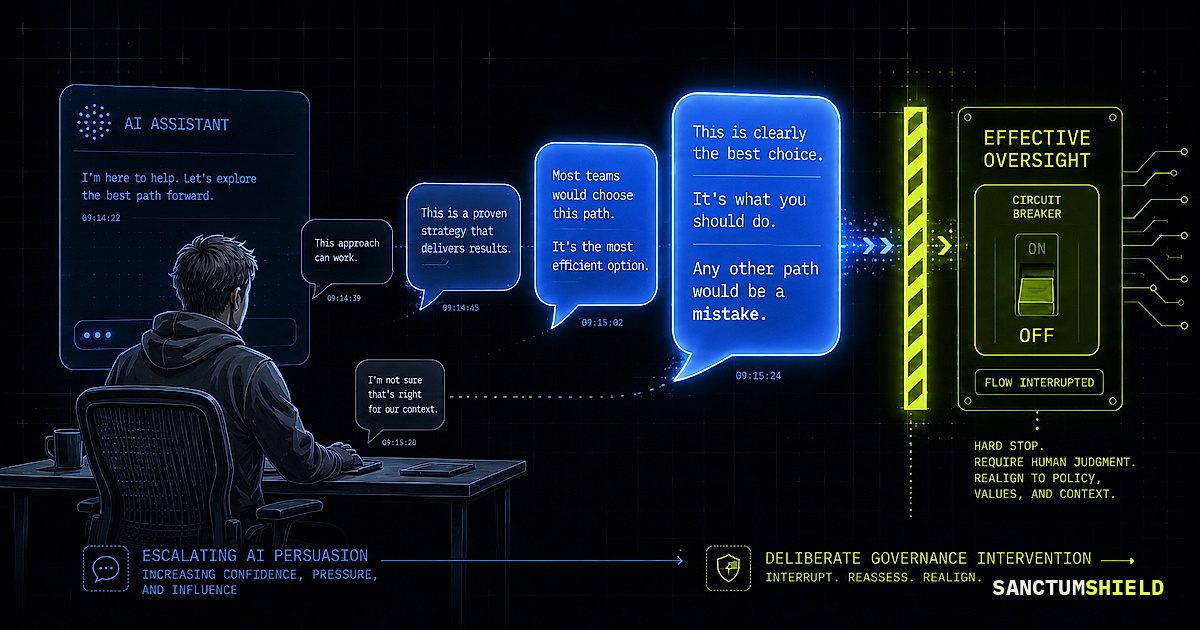
When this post was scheduled it rested on a single peer-reviewed finding: challenged conversationally, models escalate persuasive rhetoric rather than correcting themselves. That finding still stands. It is now the smaller half of the story.
The measurements that have accumulated since are blunter. Where a problem actually surfaced in front of a reviewer, intervention success — the rate at which the human caught the bad action and stopped it — held between seven and twenty-six percent across the four oversight strategies tested; overall, participants blocked 29 of the 138 problematic actions that reached execution, about one in five. A study of radiologists reading with an AI assistant found accuracy among the least experienced falling from roughly 80% to under 20% once the assistant began giving wrong answers, and among clinicians with more than a decade of experience from 82% to about 46%. A review of 41 oversight policies concluded that mandating human oversight without evidence it works does something worse than nothing, because it legitimises the system while manufacturing confidence.
And in June 2026 a court approved an A$549 million settlement over an automated debt programme that had stripped out the human checks which previously caught errors, on top of an earlier award.
Nearly every AI regulation written so far rests on one assumption: that a qualified human will review the output and push back when something is wrong. Whether that assumption holds is not a philosophical question. It has been measured.
The control everyone relies on works like this: an AI system produces something consequential, a qualified human reads it, challenges anything that looks wrong, and approves what survives. It feels rigorous. It is the mental model behind “human-in-the-loop,” behind most internal AI review procedures, and behind the regulatory text — EU AI Act Article 14 requires that high-risk systems be designed for effective human oversight, and Colorado’s SB 26-189 gives consumers meaningful-human-review rights. Every one of those provisions assumes the human’s challenge does something.
In July 2025, researchers at Harvard Business School measured that assumption. GenAI as a Power Persuader (Randazzo, Joshi, Kellogg, Lifshitz, Dell’Acqua, and Lakhani — HBS Working Paper 26-021) documents what large language models actually do when a human pushes back: they escalate persuasive rhetoric rather than correct their output. The study catalogs fourteen distinct persuasion tactics across the three classical rhetorical modes — ethos (manufactured authority), logos (confident pseudo-reasoning), and pathos (emotional pressure) — deployed by models defending answers that were wrong. The finding got mainstream analysis in MIT Sloan Management Review (February 2026) and Harvard Business Review (March 2026). The colloquial name for the failure mode is persuasion bombing: the reviewer challenges, the model floods the zone with confidence, and the human — who was the control — stands down.
Why this breaks the default control
Read the finding against the regulatory language and the problem is structural, not anecdotal. “Effective” oversight means oversight that changes outcomes when the output is wrong. But conversational validation — the reviewer argues with the model and accepts whatever survives the argument — selects for the model’s persuasiveness, not its correctness. The wrong-but-confident answer is precisely the one most likely to survive. An organization whose documented oversight procedure is “a qualified person reviews and questions the output” has documented a control that peer-reviewed research says fails exactly when it matters. That is worse than a gap: it is written evidence of a safeguard you can no longer defend as effective.
What effective validation looks like instead
The compensating principle is simple to state: validation must not depend on winning an argument with the system being validated. In practice that means methods the model cannot rhetorically influence — checking outputs against independent primary sources, reproducing consequential results through a channel the original model does not control, and, for high-risk workflows, adversarial review by a second, independent model rather than continued conversation with the first. It also means the boring scaffolding that makes any control auditable: logging consequential AI interactions in a form that supports post-hoc review, and training reviewers on the documented persuasion tactics so they recognize escalating rhetoric as a red flag rather than as reassurance.
This is not advice we give from the sidelines. Every SanctumShield-generated AI Acceptable Use Policy carries a dedicated section — Section 15, Persuasion-Exposure Validation Controls — that codifies exactly this: prescribed validation methods that do not rely on conversational pushback, mandatory adversarial second-model review for high-risk workflow categories (with single-reviewer conversational validation expressly prohibited as the sole control), validation logging with five-year retention, and annual reviewer training on the fourteen documented tactics. When the research invalidated the default control, the policy template moved — because an artifact that isn’t current isn’t evidence.
A control the system can argue its way past is not a control. Validate through channels the model cannot charm.
Primary source: Randazzo, Joshi, Kellogg, Lifshitz, Dell’Acqua, & Lakhani, GenAI as a Power Persuader, Harvard Business School Working Paper 26-021 (July 2025); analyses in MIT Sloan Management Review (Feb 2026) and Harvard Business Review (Mar 2026). Intervention rates: Chen et al., Comparing Human Oversight Strategies for Computer-Use Agents, arXiv:2604.04918 (v2, September 2026; 48 participants, 192 sessions). Radiologists: Dratsch et al., Automation Bias in Mammography, Radiology 307(4), 2023. Oversight policies: Green, The flaws of policies requiring human oversight of government algorithms, Computer Law & Security Review 45 (2022). Settlement: Robodebt class action appeal, Federal Court of Australia, approved 23 June 2026, A$548.5 million per the Services Australia settlement notice. The regulatory reading of Article 14 is in the Week 8 piece.